Timeouts that weren't the query's fault
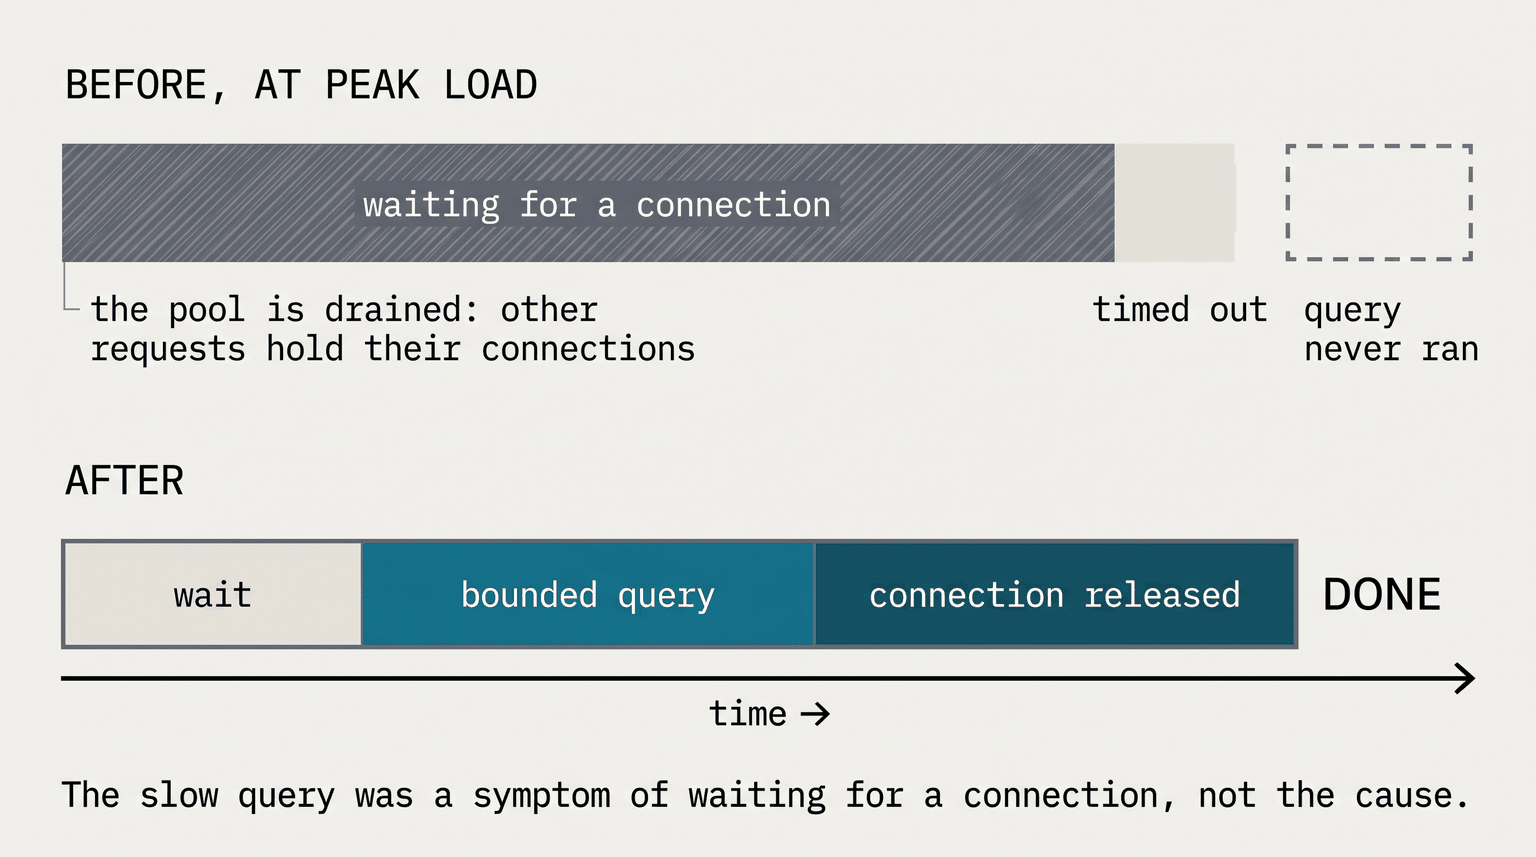
The fleet telemetry services started timing out at peak load, with a little over 300 vehicles reporting at once. Off-peak, the same endpoints were fine.
I went after the slow queries first, because that's the reflex, and it cost me most of a day. The query plans were unremarkable in isolation. The failures were happening before any query ran.
The connection pool was the real constraint. Requests were holding a connection open while iterating unbounded result sets, so under concurrency the pool drained and everything behind it queued until it timed out. The slow query was a symptom of waiting for a connection, not the cause of it.
I bounded the queries so no request holds a connection while streaming an open-ended set, then resized the pool and set timeouts to fail fast instead of queueing. Same peak load, no timeouts.
The habit I kept from it: find where the time is actually spent before optimising whatever looks slowest.